Intel’s October infrastructure push makes a useful distinction for anyone sizing servers for AI agents: executing an agent’s work is a different workload from generating its next response. Its latest Xeon throughput comparison deliberately removes model inference and external network access from the test. That makes the results easier to compare, but narrower than a claim that a complete live AI service runs several times faster.
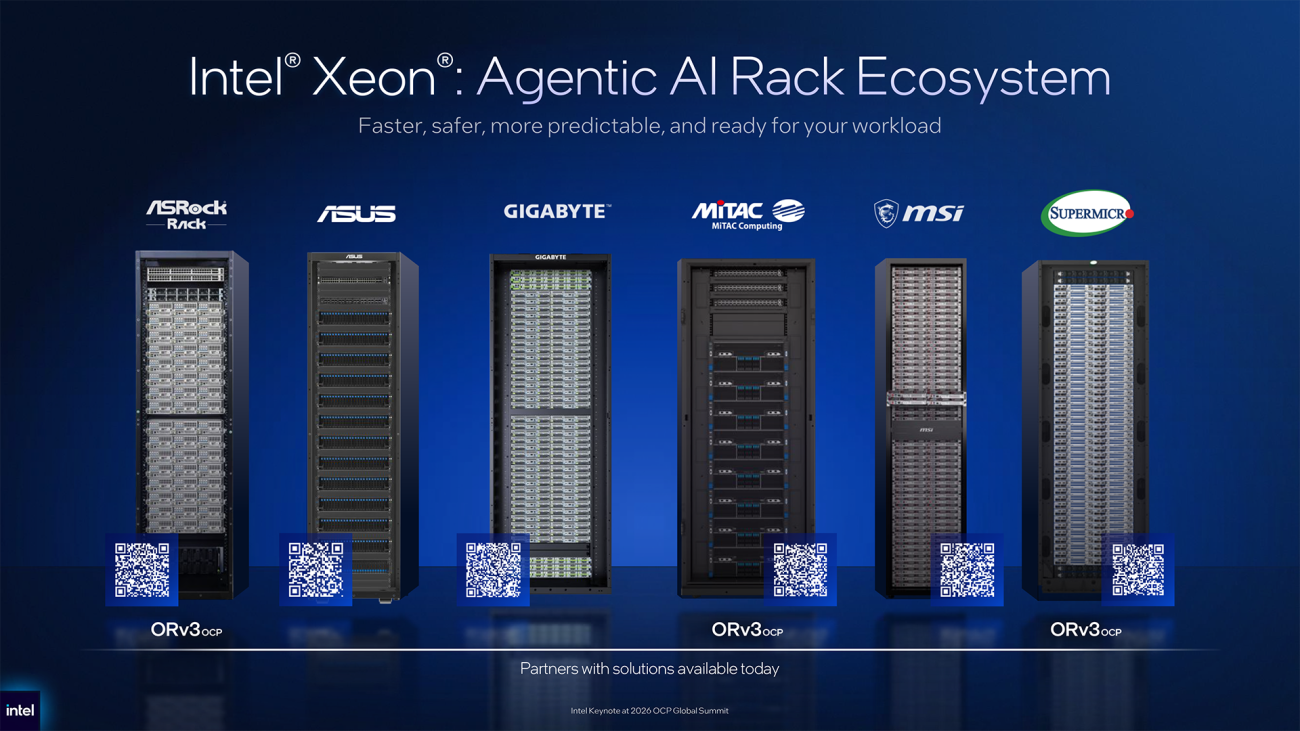
The distinction comes as Intel promotes Xeon-based rack systems at the October 12 to 15 OCP Global Summit. The company describes CPUs handling orchestration, tools and data movement alongside GPUs and other accelerators. It also advertises select Xeon 6+ configurations exceeding 46,000 cores per rack at 133.45kW total rack power. That is an infrastructure-density claim, not a count of useful agents a customer can run.
Between those two headlines sits the question a capacity plan needs to answer: which part of the actual application is waiting? More CPU capacity is relevant when tool execution or orchestration holds up a workflow. It cannot, by itself, establish the response time of a service waiting for a remote model.
The benchmark freezes the agent’s decisions
In Intel’s published methodology, a recorded Claude trajectory is replayed through a local proxy. Every platform receives the same work, rather than allowing fresh model responses to choose different commands or execution paths. Task images are already built and staged. The comparison uses 24 concurrent sandboxes over 60 minutes, with one core assigned per task and a one-thread cap per container.
Intel reports healthcare-task throughput of 1.66 times its tested AMD EPYC-based instance and 4.5 times its tested Arm-based instance. All three cloud configurations have 48 virtual CPUs and 185GB of total memory. These are Intel’s September tests, published in its October coverage, not independent SekaiTech measurements.
Replaying a fixed trajectory is a reasonable way to isolate infrastructure behavior. It avoids crediting one processor for an easier set of commands accidentally chosen by a model. It also leaves out the variable that many people associate most closely with an AI assistant: the model thinking and generating tokens. The test cannot tell a buyer how a different model, provider or live tool service would affect the complete workflow.
A separate Intel sandbox-provisioning comparison measures another part of that workflow. It uses CubeSandbox creation and deletion requests, increasing concurrency and tracking average creation latency against a 200-millisecond target. Intel reports that its Xeon 6990E+ configuration stays below that threshold until approximately 313 concurrent requests, compared with approximately 246 for its tested EPYC 9965 system.
Those figures concern making execution environments available. They are not measurements of how long an agent takes to finish a research task, nor do they establish the safety of the code executed inside a sandbox. The reported crossing points use average latency; a service with a strict slow-request limit would also need its latency distribution.
| Intel evidence | What it measures or describes |
|---|---|
| OCP rack specification | Core density and total rack power in selected configurations |
| Deterministic workflow replay | Completed tasks with model inference and external network access removed |
| Sandbox create/delete test | Provisioning latency as concurrent requests increase |
The practical consequence is to keep those measurements separate when evaluating a system. First identify whether delays arise before execution, during tool work or while waiting for the model. Then compare a matching infrastructure result with the application’s complete response time under load. A faster provisioning path may help short-lived tasks considerably while changing little for a workflow dominated by a long remote inference call.
Our earlier Intel inference-microservices coverage examined the software path for running models. These October tests address adjacent work around the model. Reading the methodology alongside the headline keeps a useful CPU result from becoming an unsupported promise about the whole agent.